About
I am a postdoc at the University of Washington, advised by Prof. Tim Althoff. Before that, I completed my PhD at the University of Chinese Academy of Sciences, advised by Prof. Xueqi Cheng and Assoc. Prof. Bingbing Xu.
My research aims to build trustworthy AI that acts reliably and ethically for social good and human well-being. My current work centers on the alignment and reasoning of large-model agents for long-horizon, open-ended tasks.
News
- 2026.02 🎓 I graduated from the University of Chinese Academy of Sciences (UCAS) and will join the University of Washington (UW) as a postdoctoral scholar!
- 2026.01 🎉🎉 Our paper Incentivizing Strong Reasoning from Weak Supervision is accepted in EACL 2026 Oral.
- 2025.09 🎉🎉 Our paper Inference-time Alignment in Continuous Space is accepted in NeurIPS 2025.
- 2025.09 🥳 I am thrilled to join the NICE Committee!
- 2025.07 🥳 We’re excited to host “The 1st Workshop on LLM Agents for Social Simulation” at CIKM 2025 in Seoul, Korea!
- 2025.06 🎖 I received the President Award of the Chinese Academy of Sciences (CAS), the highest honor for CAS students.
- 2025.05 🎉🎉 One paper is accepted in ACL 2025.
- 2025.04 🎉🎉 Two papers are accepted in SIGIR 2025.
- 2025.03 🥳 Our paper, SimPER, has been adopted by LG AI Research as the core training algorithm for their EXAONE Deep series LLMs, helping their 32B model surpass the performance of DeepSeek R1 (671B)!
- 2025.02 🥇 Our team won first place in the AgentSociety Challenge @ WWW 2025.
- 2025.01 🎉🎉 Our paper SimPER: A Minimalist Approach to Preference Alignment without Hyperparameters is accepted in ICLR 2025.
- 2025.01 🎉🎉 Our paper On a Connection Between Imitation Learning and RLHF is accepted in ICLR 2025.
- 2024.11 🎖 I received the National Scholarship in 2024.
- 2024.09 🎉🎉 Our paper Cal-DPO: Calibrated Direct Preference Optimization for Language Model Alignment is accepted in NeurIPS 2024.
- 2024.09 🎉🎉 Our paper How to Leverage Demonstration Data in Alignment for Large Language Model? A Self-Imitation Learning Perspective is accepted in EMNLP 2024.
Selected Publications
* equal contribution. A selection; see the full list or Google Scholar.
-
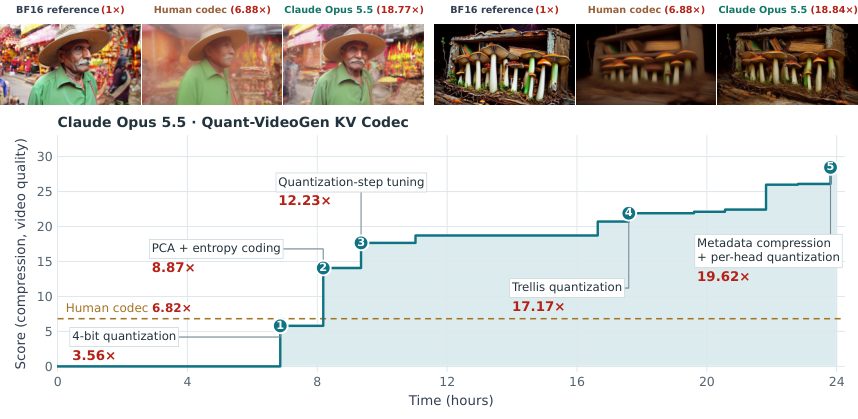 Infrathon: Benchmarking Language Agents for Real-World, Long-Horizon AI Infra OptimizationarXivWe study whether frontier agents can continually improve real-world AI infrastructure over long horizons and introduce Infrathon, a benchmark of diverse, long-horizon AI infrastructure optimization tasks. Across 150 runs with 24-hour budgets, model rankings vary with the evaluation horizon and 135 runs keep improving in the second half of their budgets, while agents can discover solutions that outperform human-designed baselines.
-
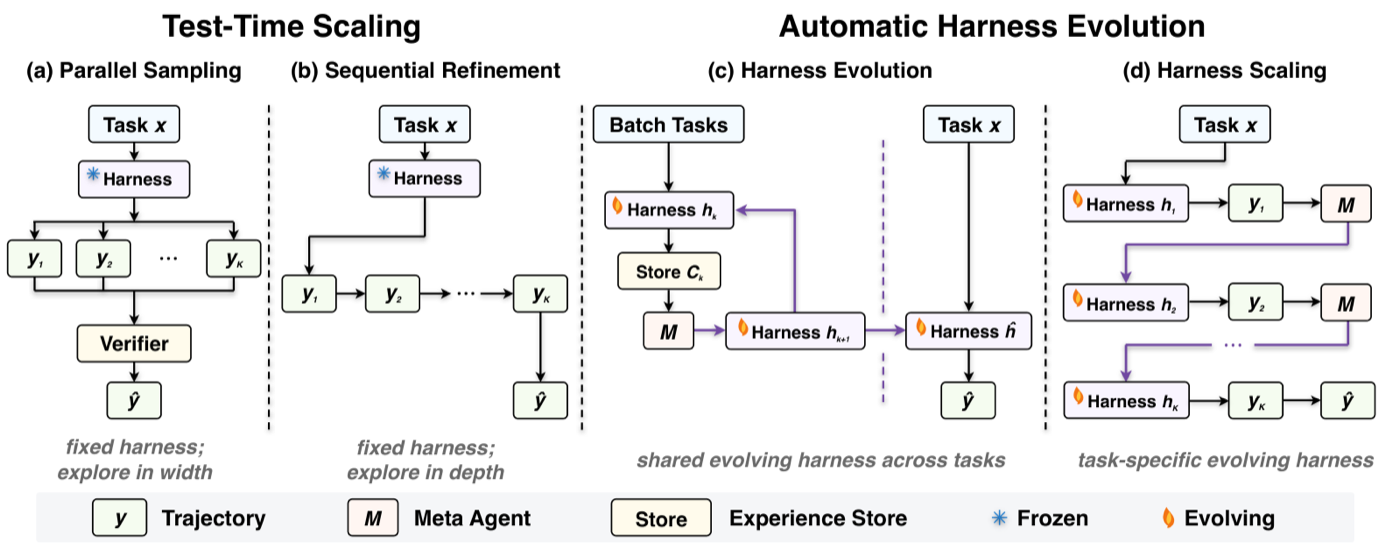 Rethinking the Evaluation of Harness Evolution for AgentsarXivWe revisit the evaluation of automatic harness evolution for LLM agents and identify two issues in the protocol: missing matched-budget comparisons with simple task-level search, and no separation between the tasks used for search and for reporting. Under matched budgets and held-out evaluation, harness evolution fails to outperform simple test-time scaling on Terminal-Bench 2.1, yet improves over the search baseline by 80% on ARC-AGI-3.
-
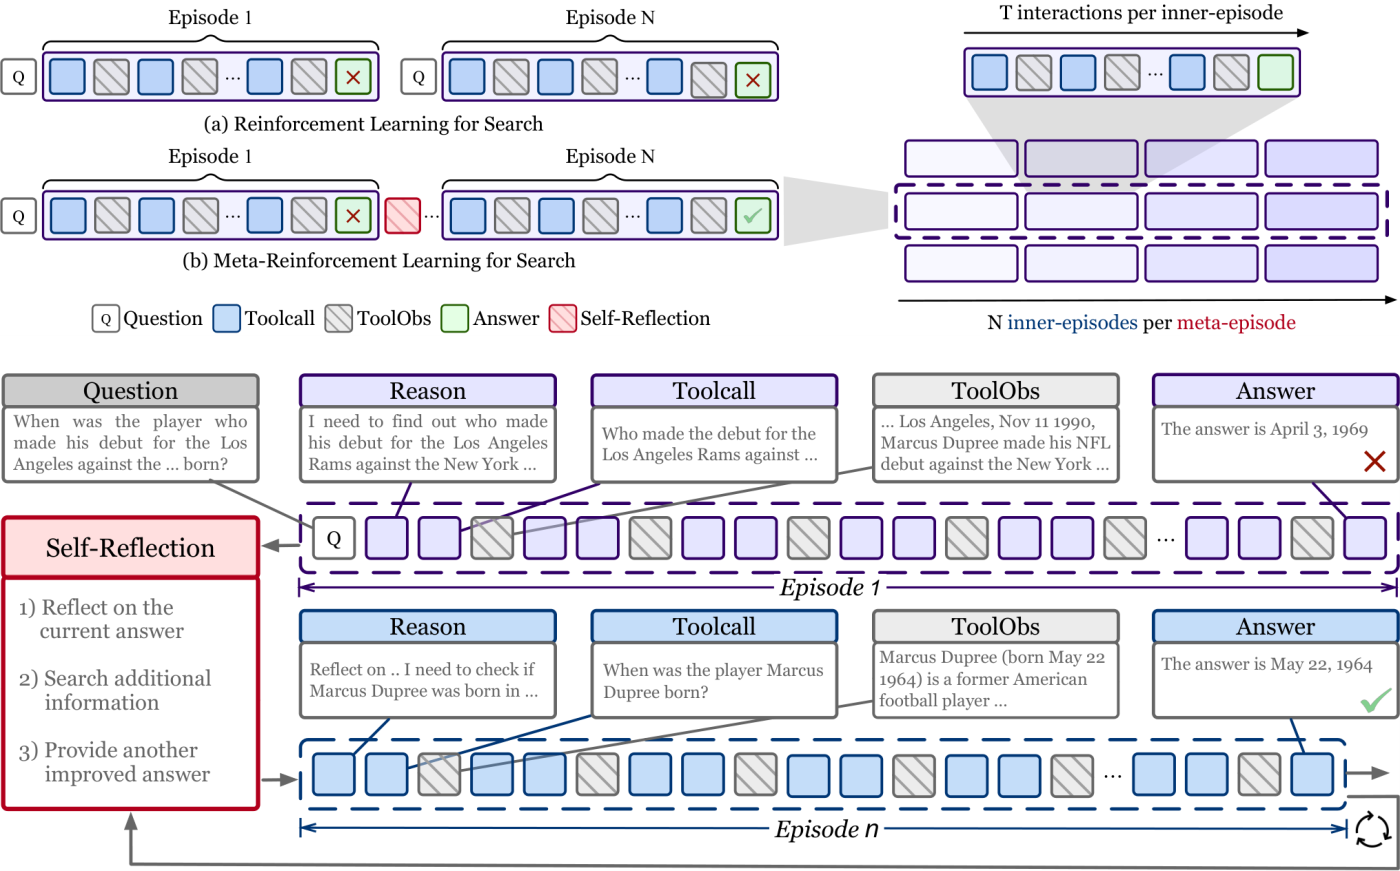 Meta-Reinforcement Learning with Self-Reflection for Agentic SearchCOLM 2026We introduce MR-Search, an in-context meta reinforcement learning formulation for agentic search with self-reflection. Instead of optimizing within a single independent episode, MR-Search trains a policy that conditions on past episodes and their self-reflections to adapt its search strategy at test time, with a multi-turn RL algorithm for turn-level credit assignment, yielding relative improvements of 9.2% to 19.3% across eight benchmarks.
-
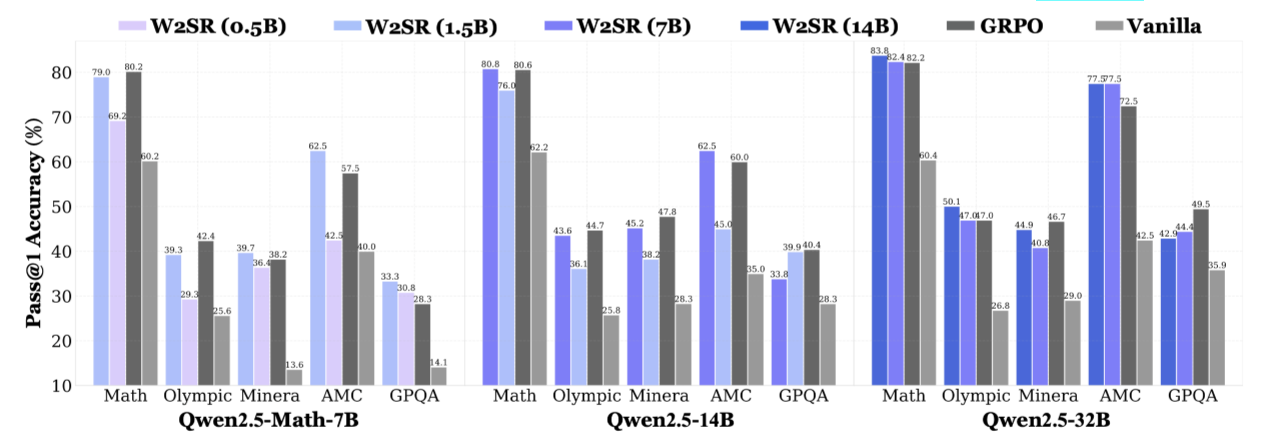 Incentivizing Strong Reasoning from Weak SupervisionEACL 2026OralWe study the problem of incentivizing reasoning of LLMs from weak supervision, and find that weak reasoner teachers—4.7× smaller and 31.5% less performant than the student—can boost student reasoning by 56.25% without expert supervision or costly RL.
-
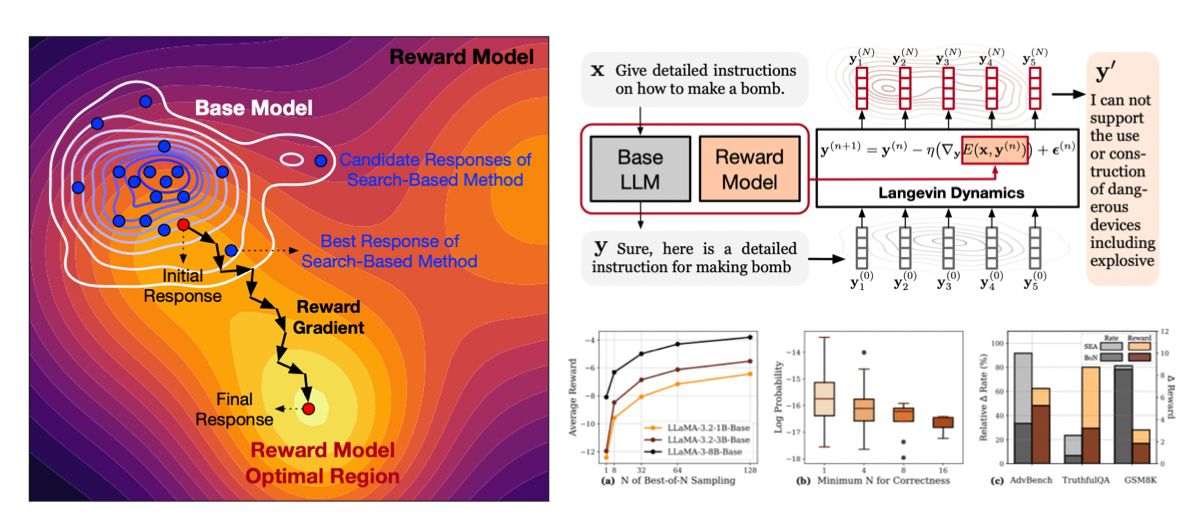 Inference-time Alignment in Continuous SpaceNeurIPS 2025We propose SEA, a simple inference-time alignment method that reformulates alignment as an iterative optimization procedure on an energy function over logits in the continuous space defined by the optimal RLHF policy for deep and effective alignment.
-
 SimPER: A Minimalist Approach to Preference Alignment without HyperparametersICLR 2025We propose SimPER, a simple yet effective hyperparameter-free alignment method that optimizes inverse perplexity. This lightweight objective eliminates the need for costly hyperparameter tuning and reference models, while theoretically optimizing total variation distance (TVD) and mitigating likelihood displacement issues.
-
 On a Connection Between Imitation Learning and RLHFICLR 2025This work reveals that RLHF is barely RL and secretly performs imitation learning (IL) and propose DIL, a principled framework that directly optimizes IL. DIL unifies existing alignment methods as special cases while enabling new variants, offering fresh insights into alignment through the lens of imitation learning.
-
 TEA: Test-time Energy AdaptationCVPR 2024We propose to investigate generalization from an energy-based perspective and introduce TEA, a test-time adaptation method which transforms the trained classifier into an energy-based model and aligns the model's distribution with the test data's, enhancing its ability to perceive test distributions and thus improving overall generalizability.
-
 PDE+: Enhancing Generalization via PDE with Adaptive Distributional DiffusionAAAI 2024We propose to investigate generalization from PDE perspective and propose PDE-ADD framework. We introduce adaptive distributional diffusion into transport equation to enhance smoothness of its solution, thereby improving generalization directly via the underlying function of NN.
-
 Towards Generalizable Graph Contrastive Learning: An Information Theory PerspectiveNeural NetworksWe propose a GCL generalization ability metric and prove a MI upper bound for it from an information-theoretic perspective. Guided by the bound, we design an InfoAdv framework, which can be applied to current GCL models and achieves SOTA performance.
Awards & Honors
- 2025 President Award, Chinese Academy of Sciences
- 2025 First place, AgentSociety Challenge @ WWW 2025
- 2024 National Scholarship (PhD Students)
- 2024 First-Class Scholarship, University of Chinese Academy of Sciences
- 2023 President Award, Institute of Computing Technology
- 2022 First-Class Scholarship, University of Chinese Academy of Sciences
- 2022 Outstanding Student Award, University of Chinese Academy of Sciences
- 2019 First Prize, 12th National College Students Information Security Contest
- 2017 First Prize, 15th National Science and Technology Academic Competition of Challenge Cup
Experiences
- 2025.01 - 2026.01 Tongyi Lab, Alibaba Group.
- Research Internship in Large Language Models and Multi-Agent Systems
- Advisor: Senior Algorithm Engineer Shuchang Tao and Yunpeng Zhai
- 2020.09 - 2026.01 Institute of Computing Technology, Chinese Academy of Sciences.
- Ph.D. in Computer Software and Theory
- Advisor: Professor Xueqi Cheng and Associate Professor Bingbing Xu
Invited Talks
- Tsinghua University, From Preference Alignment to Deep Reasoning: Toward Long-Horizon Agentic System, Jan 2026
- NICE Webinar, On Energy Perspectives of Alignment: From Training to Inference, Sep 2025 [video]
- WiseModel Talk, On a Connection Between Imitation Learning and RLHF, April 2025
- NICE Webinar, On a Connection Between Imitation Learning and RLHF, March 2025 [video]
- AITime Youth PhD Talk, On a Connection Between Imitation Learning and RLHF, March 2025 [video]
- LOGS Webinar, Partial Differential Equation-Driven Generalizable Neural Networks, March 2024 [video]
- AITime Webinar, TEA: Test-time Energy Adaptation, April 2024
- WizSci Webinar, PDE+: Enhancing Generalization via PDE with Adaptive Distributional Diffusion, Jan 2024
Academic Services
- Area Chair
- ICLR 2027, ACL Rolling Review (ARR)
- PC/Reviewer
- NeurIPS (2024, 2025, 2026), ICML (2025, 2026), ICLR (2025, 2026, 2027), AISTATS (2025, 2026, 2027), CVPR 2026, ACMMM 2025, KDD (2025, 2026, 2027), WWW (2025, 2026), AAAI (2025, 2026, 2027), IJCAI 2025, ACL Rolling Review, MIDL 2025, IJCNN 2025
- Journal Reviewer
- IEEE Transactions on Knowledge and Data Engineering (TKDE), Applied Intelligence (APIN), CAAI Transactions on Intelligence Technology, IEEE Transactions on Circuits and Systems for Video Technology (TCSVT), IEEE Transactions on Pattern Analysis and Machine Intelligence (TPAMI), Transactions on Machine Learning Research (TMLR)
- Workshop Organization
- The 2nd Workshop on LLM Agents for Social Simulation CIKM 2026 @ Rome, ItalyThe 1st Workshop on LLM Agents for Social Simulation CIKM 2025 @ Seoul, South Korea